
GrantTap guide · · 12 min read
From Send to Started: understand an agent message's journey
A visible message, a relay receipt and agent activity establish different facts. A practical GrantTap guide to delayed requests, fresh Working status, safe retries and meaningful latency measurements.
You send a short instruction from your phone, see it appear in the conversation, and expect the coding agent to react. Instead, the delivery panel says that the message is saved, while the task looks busy. A minute passes. Pressing Send again feels reasonable, but it can create another instruction without explaining the first one. The useful question is where the original request stopped and which component can prove the next step happened.
GrantTap connects a human decision on one device to work performed by an agent on a computer. That makes delivery part of the product, rather than a detail hidden behind a chat bubble. This guide explains how to read that route, how to recover a delayed message, and how to judge responsiveness without confusing network activity with useful execution. Examples describe diagnostic situations; they are not promises that every provider exposes the same controls or events.
One instruction crosses several boundaries
Start with a concrete request: ask the agent to check the tests for an existing branch. The phone creates an outgoing instruction for a specific Task and computer. A transport can accept its encrypted envelope before the destination computer is available. The computer can then receive the instruction before its provider process is ready to take another turn. Finally, the agent can start work before producing any useful answer. Those boundaries explain why a single green indicator cannot describe the whole journey.
A Task is the stable human context for that journey. Its title helps you recognize the work, but routing also needs identity: the intended Task, destination computer, provider session, and original message. If a second computer happens to be online, that does not make it an interchangeable destination. Its checkout, credentials, local changes, and permission state may differ. A delivery diagnostic should preserve the original route while investigating it, rather than quietly moving work to another environment.
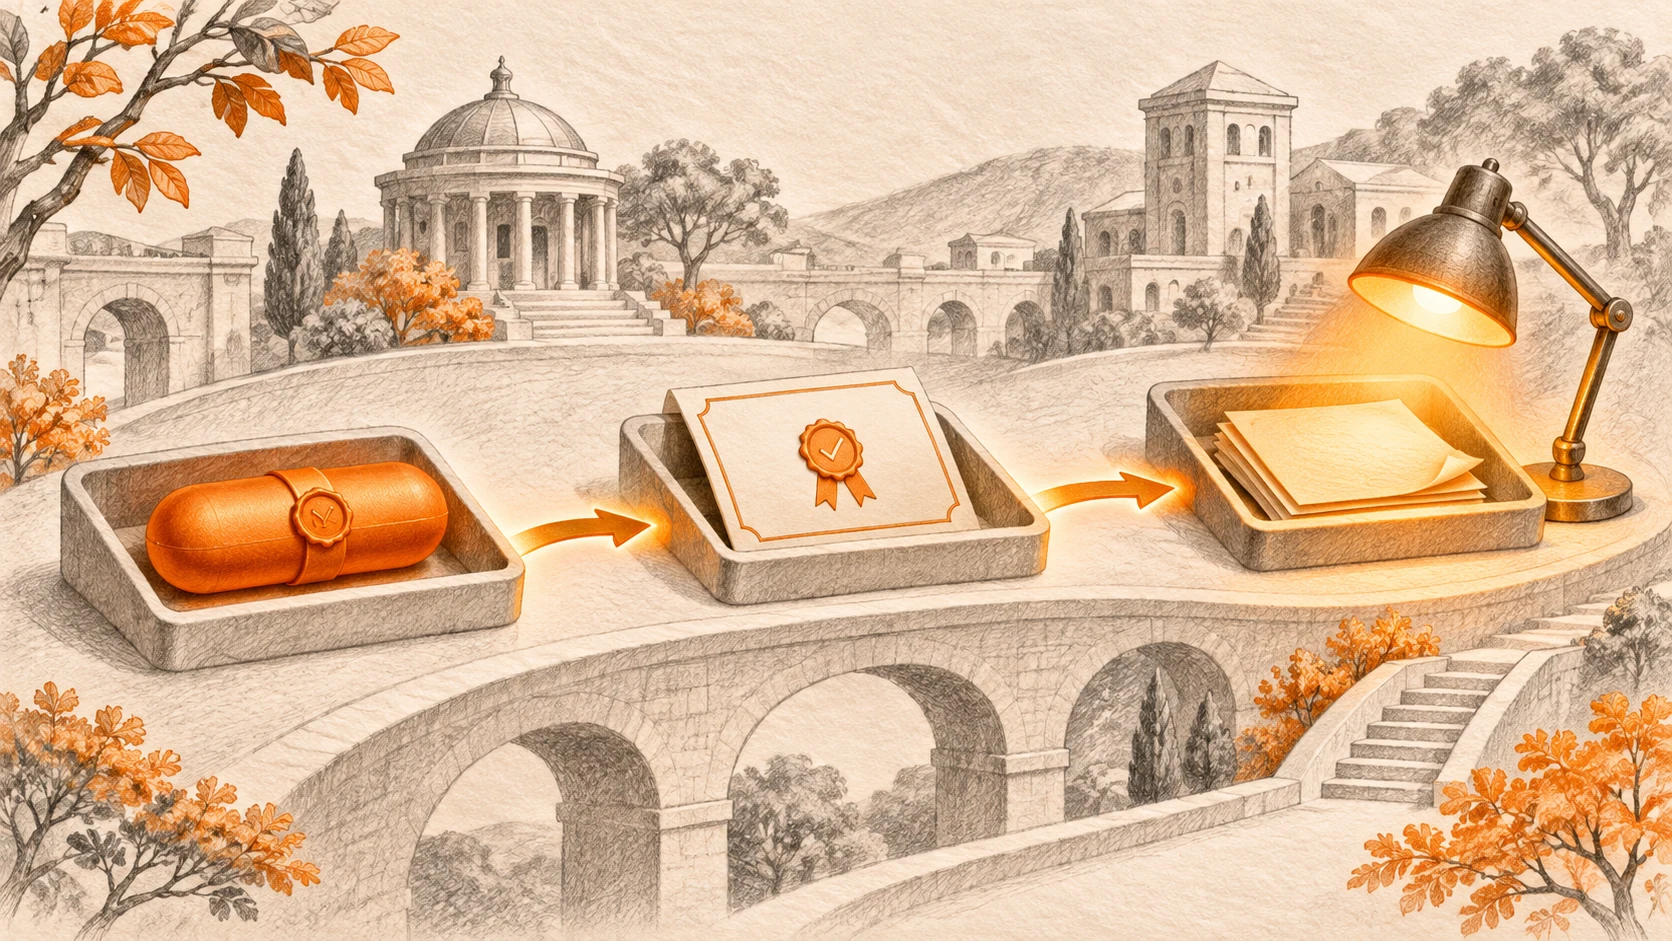
The earlier guide to waiting messages explains the queue and encrypted relay. Here the focus is narrower: what a receipt permits you to conclude. A record at one stage is evidence about that stage. It becomes evidence about a later stage only when the later component supplies its own acknowledgment. This simple rule turns a vague stalled chat into a sequence of questions you can actually answer.
A visible bubble records your intent
The first useful acknowledgment is local. The composer accepted your text and the conversation now contains it. That matters because it protects the instruction from a disappearing draft and gives you something concrete to inspect. It does not establish that the computer received anything. A phone may be offline, its connection may be reconnecting, or the task route may be waiting for a computer that is asleep.
Treat an outgoing bubble as the beginning of the operation. If an interface immediately marks the entire task Working merely because the bubble was added, it merges two different facts: your intention and the agent's execution. This can hide the most important failure. You are waiting for delivery while the screen suggests that the agent is thinking. A useful interface keeps pending delivery visible without manufacturing an execution event.
The reverse matters as well. An already running agent should remain visibly active when you send a follow-up. Your message does not erase existing work. If the provider supports steering during execution, that capability needs its own route and acknowledgment. If it accepts only a later turn, the instruction belongs in a queue. A generic Send button cannot honestly imply that every provider supports interruption, steering, and immediate execution in the same way.
A relay receipt establishes a transport fact
When the relay confirms storage, the encrypted envelope has reached that service. This is useful during disconnection because the phone may no longer need to remain open for the queue to retain an accepted request. The confirmation still says nothing about whether the target computer can currently run its agent. Storage, retention, expiry, and delivery are separate responsibilities, and their limits should remain understandable in the interface.
GrantTap's security explanation describes the distinction between ciphertext transport and readable content on authorized endpoints. Encryption protects the contents along that route; it does not turn a storage receipt into a work receipt. A relay can correctly retain a message while the destination needs a provider login. It can also be reachable from the phone while a computer's network blocks or delays its own connection.
If a message remains at this stage, inspect connectivity and destination identity first. Repeatedly changing the instruction is unlikely to repair a sleeping computer or an unavailable route. Keep the original message and look for a newer computer receipt. That preserves the best evidence for diagnosis and reduces the chance of delivering several almost identical requests when the destination reconnects later.
Computer receipt still precedes agent activity
A computer acknowledgment moves the investigation forward. It establishes that the local bridge saw the request. Now the relevant questions concern that host: is the selected provider installed, authenticated, permitted to use the checkout, and able to accept the requested operation? A machine can be fully online while one provider is unavailable. The operating system, GrantTap runtime, and provider CLI have separate lifecycles.
Consider a provider that has signed out after an update. The bridge can receive the message immediately, but starting the provider might produce a login requirement. Waiting longer will not satisfy that requirement. The useful next action is a provider-specific sign-in flow on the intended computer, followed by a check of the same request. A connection indicator for the bridge should not conceal a blocked provider identity.
Agent activity is a further observation. It might be a new native conversation entry, a tool event, or another supported signal associated with that Task. The exact evidence depends on the provider integration. Its absence should remain an explicit uncertainty. Computer receipt is real progress, but a delivery panel should not translate it into an assertion that the model read and understood the instruction.
Working needs a source and a time
An execution label is more useful when it comes with freshness. A recent Working observation says something different from a catalog snapshot collected before the last answer. If an older session list arrives after newer chat activity, it should not restore an obsolete state. Likewise, scrolling through old messages should not change whether the current root task is running. History is evidence about earlier events, not an authority over current execution.
This creates a practical requirement for any agent controller: observations need an ordering rule. The rule must refer to the relevant source and session, rather than treating every packet arrival as the newest truth. An old response can arrive late because the network was slow or because a larger scan took longer. Arrival order alone does not tell you which observation reflects later work.
From the user's side, read timestamps and newly arriving activity together. A fresh tool event helps establish continuing work. An old Working badge with no current observation deserves inspection. The controller should give you that distinction directly. You should not need to infer the health of a provider from a spinning animation or from the fact that the chat composer is disabled.
A finished reply can leave real background work
The opposite transition also deserves care. A model can finish a visible reply while its process still owns a running command, a background build, or another operation. A completed paragraph is evidence that the model ended that response. It does not necessarily mean the entire provider invocation has returned or that another CLI can safely operate on the same session and checkout.
Imagine an agent that reports its changes while a build continues. Starting a second invocation immediately could make both processes inspect or modify the same files. Even a short status question can trigger more commands when the provider resumes. A queue therefore needs to respect physical execution ownership in addition to the presentation state shown in the conversation. A native end-of-turn marker alone may be insufficient to release that ownership.
This is why faster status updates and safe queue admission are different engineering tasks. A controller can improve freshness without pretending that active work has ended. If the provider supports a documented steering mechanism, use it within its actual boundary. Otherwise, show why the next turn is waiting. Accuracy is more useful than making the queue look empty while two processes compete for the same task.
Refreshing and retrying answer different questions
Refreshing asks what happened to an existing message. Retrying attempts delivery again under the system's retry rules. Running again may create a new execution of an instruction that already completed. Those actions deserve different labels because their consequences differ. When the result is uncertain, the first step is usually to inspect the original request rather than immediately create another operation.
A strong implementation keeps identity across reconnects and safe retries. The receiver can then recognize that two transport attempts refer to one logical instruction. This does not provide magical exactly-once execution across every possible failure. There can still be a gap between a side effect occurring and its receipt becoming durable. It does, however, provide a concrete basis for deduplication and for explaining uncertainty without multiplying messages.
When investigating, record the original request identifier privately and compare it with the destination's history. If the original text already appears once in the native conversation, an extra send is unlikely to be the right recovery. Look instead for provider activity, an unanswered approval, a login requirement, or a result that has not synchronized back. Support reports should include those stages without exposing tokens, pairing codes, or private source files.
Measure the interval that actually feels slow
Delivery latency contains several intervals: local acceptance, relay acknowledgment, computer receipt, provider start, first activity, and meaningful result. A single total can identify a poor experience but cannot locate its cause. A minute spent waiting for a computer to wake is different from a minute spent running tests. Making encryption faster will not remove either wait, although it can reduce processing costs once packets are flowing.
Use a small, harmless observation task when measuring the route. Keep the same destination and avoid edits, installations, or network downloads during the probe. Observe several attempts under normal conditions and retain the timestamps for each stage. Report the environment as well: a local simulated phone client is useful for isolating transport code, while a physical phone on a mobile network exercises additional conditions. Neither measurement should be presented as the other.
The relevant question for a product team is which interval it can improve without inventing evidence. Smaller current-chat updates can reduce time spent waiting for a full session scan. Avoiding unchanged payloads reduces repeated work. Bounded caching can reduce repeated cryptographic setup. Each optimization needs its own verification, while the final user experience still needs an end-to-end check under realistic connectivity.
A network change should preserve one request
Moving from Wi-Fi to a mobile connection is a useful everyday test. The transport may reconnect, but the user's intention should keep the same identity. The conversation should retain the pending message, and a later receipt should update that message's history. If a second bubble appears merely because the connection changed, inspect whether the interface created another logical request or only displayed another transport attempt. Those are different defects with different recovery paths.
Test a return to the app as well. A cached delivery panel should reconcile against fresh information without erasing the original instruction. The most helpful outcome is a clear explanation of the current boundary, including expiry when it applies. A disconnected phone does not prove a disconnected computer, and reopening the interface should not silently execute an already completed instruction again.
Recover in the order the evidence suggests
Suppose the relay receipt is recent but there is no computer receipt. Check whether the intended computer is awake and whether its managed runtime is connected. Suppose the computer receipt exists but there is no agent activity. Inspect provider authentication, a pending approval, and actual process ownership. Suppose activity exists but the phone has no result. Investigate synchronization of that same Task rather than creating another conversation to obtain a fresh answer.
Maintenance can help, but a restart is an operation with consequences. Restarting a bridge differs from stopping a provider that is compiling code. Clearing a derived cache differs from removing retained task history. Before choosing either action, determine what work is active and what data the action affects. Use the smallest repair that addresses the observed boundary, then verify the original request rather than assuming that a green connection fixed everything.
The goal of this procedure is a conversation you can trust. Your instruction should appear once, its delivery history should remain inspectable, and the result should return to the same Task. When something is still unknown, the interface should name the missing acknowledgment. That is the foundation for a responsive mobile agent workflow: fewer repeated guesses, clearer recovery, and execution state grounded in what the computer actually observed.